A name is not a threshold
Assumes A colour has a name and A threshold is not a unit.
Two questions get asked about a pair of colours and they sound like the same question. Can these be told apart? is a threshold, it has been measured since the 1940s, and on this site it is about one unit of CIEDE2000. Would anybody call these the same colour? is a vocabulary, and until the last essay this site had no way to ask it at all.
They are not the same question, and the gap between them is a factor of ten.

The claim
A name is worth about ten thresholds, and the number is not constant.
At a moderately saturated orange, the nearest direction in which the name changes is 8.3 ΔE00 away and the furthest is 21.4. At a mid green it is 10.8. At a pale pink, 9.4. A just-noticeable difference in the same units is about one.
Three consequences:
- A specification and a conversation are an order of magnitude apart. A supplier held to ΔE00 ≤ 1 is being asked for a match ten times tighter than the resolution of the word that names the colour. Everything inside a name is a matter for measurement, because language cannot see it.
- The ratio between the two is not fixed anywhere. It varies by more than three across one plane of the space, so there is no conversion factor between “one unit” and “a different colour” and there could not be one.
- And this model has no term for the effect the literature is actually about. Categorical perception is the claim that a difference straddling a boundary is easier to see than an equal difference inside a name. Nothing in a nearest-centroid model can produce that, the model does not produce it, and the absence is asserted here rather than glossed over.
What a naming resolution is
The soft version of the naming model gives every colour a probability for each of the eleven basic terms. The probability that two colours draw the same name is then the agreement of two independent draws — which is what a naming experiment measures when it asks two people, or the same person twice.
The naming resolution at a colour is the smallest ΔE00 step, in any direction, after which that agreement has fallen to half.
One detail in that definition is load-bearing and was got wrong first. Agreement has to be measured relative to a colour’s agreement with itself, which is not one for any boundary of finite width: at a soft boundary even an exact repeat of a stimulus draws two different names sometimes. Without the normalisation the criterion trips at zero distance for a vague enough vocabulary, and the first version of this measurement reported that a vaguer vocabulary has a finer naming resolution — which is nonsense, and was produced by comparing an absolute agreement against an absolute criterion.
With the normalisation the model’s one free parameter stops deciding anything. Making the boundaries four times softer moves the resolution from 8.76 to 8.57 units at the test colour — a couple of per cent. What sets the resolution is how far apart the centroids are, and the centroids are quoted.
Against the threshold
The comparison the essay exists for needs both numbers in the same units, and they are: CIEDE2000 was built so that one unit is about one just-noticeable difference, which is the whole justification for the formula’s existence.
That equivalence is itself soft — a threshold and a suprathreshold difference are two different measurements and the contours they produce are not the same shape — but it is soft by a factor of about two, and the gap being measured here is a factor of ten.
So: inside a single colour name there are of the order of a thousand distinguishable colours, if the name’s radius is ten units and a threshold is one and the space is three-dimensional. A word is not a fine instrument. It was never trying to be.

What categorical perception would need, and what is not here
The interesting version of the claim is not about words at all. It is that discrimination is better across a boundary: two chips a fixed physical distance apart are told apart more reliably when one is called green and the other blue than when both are called green.
That is a claim about a threshold varying with a category, and it has been reported, disputed, replicated in some conditions and not in others, and shown to depend on which visual field the stimuli are presented in — which is one of the more remarkable results in the area and is not something a colour metric was ever built to express.
A nearest-centroid model cannot produce it. The model’s thresholds are the metric’s thresholds; the metric knows nothing about the eleven points; and adding the eleven points changes what a colour is called without changing by one part in a thousand how far apart two colours look. The two layers do not interact, by construction.
Stating that as an absence rather than leaving it implicit is this site’s habit, and there are now four such absences: binocular mixing, why a stabilised image fades, why dither works, and this. assertNamingIsNotExplainedHere is written so that a future revision which starts predicting a category effect stops the site from building and forces somebody to decide whether the model has become a theory or merely been fitted.
What was computed, and how
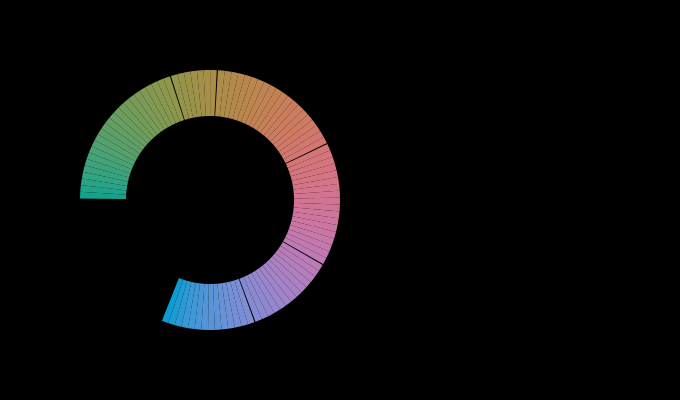
The resolution map walks twelve directions out of each sampled colour in quarter-unit steps, evaluates the normalised same-name agreement at each step, and reports the ΔE00 at which it first falls below a half. Points outside the sRGB gamut are skipped rather than extrapolated, which is why the map has ragged edges.
The map is quantised to eight levels and merged along rows before it is drawn, which is the fleet’s standing rule about fields of cells: eight hundred rectangles is thirty kilobytes of SVG and a few dozen merged runs is five, for a picture nobody can tell apart.
The variation across the plane is the range of that map, and it is 3.4-fold at L* 60 — from about six units in the crowded region where pink, purple and red meet to over twenty in the middle of green, which has no near neighbour in any direction.
And the independence is the correlation from the previous essay, read the other way round. Boundaries do sit somewhat where a degree of hue buys the most difference — −0.42 to −0.64 depending on the ring — but a correlation of that size accounts for under a fifth of the variance, and none of the arc widths, which stay unequal by a factor of 4.5 after the metric has been given its say.
Where the model stops
The boundary width is not measured, it is chosen. The softmax temperature is stated with a range and the conclusions hold across it, which is the best this file can do without naming data. What it cannot do is predict how sharp a real boundary is, and a real boundary’s sharpness is exactly what a categorical perception experiment measures.
One observer, one vocabulary. The eleven centroids are an average over speakers of one language, and the resolution computed from them is a property of that average. Two speakers’ focal reds differ; nobody here knows by how much. What is known, from the observer population, is that two people’s eyes differ by more than a ΔE00 on an ordinary pair — which means part of the disagreement any naming study measures is optical rather than linguistic, and no study this site has read separates the two.
And the resolution is a distance, not a direction. The map reports the nearest direction in which the name changes, which is the conservative reading. The furthest direction is two to three times larger at most points, so a step of a given size may or may not change the name depending entirely on which way it goes — a shape effect the single number hides, and the same shape effect that makes a tolerance a shape rather than a number.
The generalisation
The sentence worth carrying is: language resolves colour about ten times more coarsely than the eye does, and every quantity on this site lives in the gap.
That is why colour needs a measurement system at all. If words resolved colour at threshold there would be no reason to build CIE XYZ, no reason for a tolerance, and no colour order system — a person could simply say which colour they meant. The entire apparatus exists to address the region below the resolution of speech.
And it explains a persistent frustration in applied colour that is usually blamed on carelessness. A client who says two samples are “the same red” and a spectrophotometer that reports ΔE00 4.2 are both right: four units is well inside the radius of the word and well outside any specification. The disagreement is not about the colours. It is that one party is using an instrument with ten times the resolution of the other’s, and neither has said so.
Who found it, and when
The naming-and-discrimination question is Kay and Kempton’s, in 1984, and the design is the memorable part: speakers of English, whose vocabulary puts a boundary between green and blue, were compared against speakers of Tarahumara, whose does not, on triads of chips spanning that region. The English speakers’ judgements shifted toward their category boundary and the Tarahumara speakers’ did not — and the effect went away when the task was rearranged so that naming could not be used as a strategy.
Roberson and colleagues took the same question to Berinmo and Himba speakers in the 1990s and 2000s and found category effects that followed those languages’ boundaries rather than English ones, which is the strongest form of the argument and the one most argued about.
And the lateralisation result — that the effect appears for stimuli in the right visual field, which projects to the language-dominant hemisphere, and is weaker or absent in the left — is the finding that made the area impossible to dismiss as a task artefact. It is also the finding furthest from anything this site can compute: it is about which half of a brain is being asked.
The threshold half of the comparison is older and quieter. MacAdam measured discrimination in 1942, the CIE fitted CIEDE2000 to suprathreshold judgements in 2000, and neither exercise asked a single participant what any of the colours were called.
That separation is worth dwelling on, because it is not an oversight and it is not obviously wrong. A discrimination experiment is trying to measure the visual system with the observer’s vocabulary held out of the way, and asking somebody to name a chip is a good way to contaminate the measurement — the Kay and Kempton result is precisely a demonstration that naming leaks into judgement when the task permits it. So the two literatures have kept apart for a defensible methodological reason, and the cost of that is the one this essay is about: after eighty years there is no single reference in which the resolution of a word and the resolution of the eye are quoted in the same units.
Putting them in the same units is arithmetic once both exist, and it took one function of twenty lines. What it needed was somebody to want the ratio.

What the pictures cannot show
They cannot show a boundary being crossed. The map shows how far a boundary is; it cannot show what happens at one, because in this model nothing happens at one. A picture of the categorical effect would need two pairs of patches at equal ΔE00, one straddling a boundary and one not, with a claim about which is easier to tell apart — and the claim would be an assertion this site cannot make.
And they cannot be read by two people the same way. Every figure here is drawn at centroids somebody else’s speakers pointed at, on a display neither this site nor the reader has characterised, through a lens whose density is a function of the reader’s age. Three sources of disagreement, none of them the one the essay is about.

The two counts differ by twenty-one, and the reason is a cube
This essay states how many distinguishable colours fit inside a name twice, and the two answers are not the same. The first, from the radius, is of the order of a thousand. The second, from dividing a display’s count among eleven words, is of the order of a hundred thousand. A factor of a hundred between two estimates of one quantity in one essay is the kind of thing that has to be either reconciled or withdrawn.
It reconciles, and the reconciliation is the essay’s own point about shape, raised to the third power.
A count of colours is a volume, and a volume goes as the cube of whatever length is fed to it. The first estimate uses ten units, which is the nearest distance from a colour to a boundary — the conservative reading the resolution map deliberately reports. The second uses a whole territory, whose reach is the furthest distance. The map’s own numbers give both: black’s radius is 10.5 units and green’s is 29.0.
| radius used | ball, in threshold-sized cells | × 11 names |
|---|---|---|
| 10.5, black | 4,850 | 53,000 |
| 29.0, green | 102,000 | 1.12 million |
The second line lands on a million colours across the gamut, which is the right order for a display’s distinguishable count and is where the hundred-thousand figure comes from. The first lands two orders below it. Neither is wrong; they are answers to different questions, and the ratio between them is 21.1 — which is (29.0 / 10.5)³ to three figures, so the entire discrepancy is the cube of the ratio between the smallest name and the largest.
That is worth more than a correction, because it re-scales a caution the essay already makes. The observation that the nearest direction is two to three times shorter than the furthest is presented as a shape effect the single number hides. Stated as a distance, a factor of 2.6 sounds like a qualification. Stated as a count — which is how anyone actually uses it, when asking how much room a word has — it is a factor of 17. At the orange, an ellipsoid with semi-axes 8.3 and 21.4 holds four times what a ball of 8.3 holds, and that is before the third axis is allowed to be the longer one.
So the honest form of this essay’s headline claim is a range rather than a number. A name holds somewhere between five thousand and a hundred thousand distinguishable colours, depending on the name and on which radius is meant, and the threefold spread across one plane of the space becomes a thirty-ninefold spread once it is counted rather than measured. The factor of ten between a word and a threshold survives all of this untouched, because it is a ratio of distances and never becomes a volume. It is only the thousand that has to be handled with the shape in view.
The general form: a linear tolerance quoted about a non-spherical region understates the region’s contents by the cube of its aspect ratio, and a colour region is never spherical. The same arithmetic applies to a supplier’s ΔE00 ≤ 1, one unit and a hundredth of the scale down.
Where the ladder goes next
The nearest unfinished piece is the one this essay had to declare absent: a mechanism by which a category could change a threshold. That needs a second stage that knows about both, and the only such thing on this site is the opponent decomposition, which knows about statistics of natural spectra and nothing about words.
The second is the observer question, and it is answerable. A naming study’s disagreement between speakers has an optical component that is computable from the population in this phase’s other half — so somebody could ask how much of the spread in reported focal colours is the lens rather than the language. The answer would be a lower bound on how much of colour naming is not about naming.
And the third is what the whole vocabulary looks like from underneath: eleven terms, of which three lie on a line of zero chroma and hold a fifth of the gamut. Whether an eight-plus-three structure is a fact about English or about the visual system is the question the World Color Survey exists to answer, and this site cannot open it.
Where this goes next
 A colour has a name
Every quantity here is a number, and the question a reader arrives with is what colour something is called. The eleven basic terms of English divide the space into territories that differ by a factor of five, the metric accounts for fifteen per cent of that, and one of the eleven focal colours cannot be shown on this page at all.
 A threshold is not a unit
MacAdam measured the smallest difference anyone could detect. ΔE2000 was fitted to how far apart plainly different colours look. The two are quoted interchangeably, and the contours they produce are not even the same shape.
 Where the formula is not smooth
A colour difference formula is a distance, and a distance ought to vary gently. CIEDE2000's does not everywhere — it carries a hue-rotation term with a hard edge in it, and the discontinuity sits where a great many industrial samples live.
What this makes readable
Essays that name this one as a prerequisite.
Named alongside this one
Essays reaching for the same objects. Nobody chose these; they are what the index of named objects makes visible.
- There is no word for that colour assertion · basic colour terms · categorical perception · ciede2000 · individual variation · naming · perceptual uniformity · specification
- Which of two is worse ciede2000 · δe · just-noticeable difference · perceptual uniformity · specification · threshold · tolerance
- A difference has no place ciede2000 · δe · just-noticeable difference · specification · threshold · tolerance
- A difference is not a distance assertion · ciede2000 · δe · perceptual uniformity · specification · tolerance
- How many colours are there ciede2000 · δe · just-noticeable difference · perceptual uniformity · threshold · tolerance
- A catalogue is not a vocabulary basic colour terms · δe · naming · perceptual uniformity · specification
What links here
Every essay whose body links to this one.
The objects this essay names
Each one links to every other essay that touches it.
AssertionBasic colour termsCategorical perceptionCIEDE2000ΔEIndividual variationJust-noticeable differenceNamingPerceptual uniformitySpecificationThresholdTolerance