Concept

The von Kries transform — where it appears

The oldest model of chromatic adaptation: three independent gains, one per channel, chosen so that the white maps to the white. Everything about how well it works turns on which three axes the gains are applied along, a choice the model itself does not make.

Named by 47 essays across 8 fields — each of them below, with the objects they name alongside it.
One reflectance, two illuminants, two colours. A reflectance peaking near 580 nm, and the colours it produces under D65 and A. The object has not changed. The light has, and colour is a property of the pair.

Constancy is the default

A sheet of paper looks white in daylight and white under a tungsten lamp, although the light reaching the eye differs enormously. The visual system is solving one equation with two unknowns, and it solves it by assumption.

brain · Appearance
Four adaptation transforms, measured against CAT16 (D65 to D50). Twenty-seven colours moved from D65 to D50 by each transform, compared with the current recommendation. Bars are the worst disagreement in CIELAB, the number beside each is the mean. Plain XYZ scaling — still shipping, still called von Kries by people who have not read von Kries — misses by up to ΔE 13.7, which is many times any tolerance a supplier would be held to.

Four ways to move a white point

Every chromatic adaptation transform is the same three lines with a different matrix. The matrices disagree by more than any tolerance a supplier is held to, and the oldest one — still shipping, still called von Kries — is not a cone basis at all.
brain · Appearance
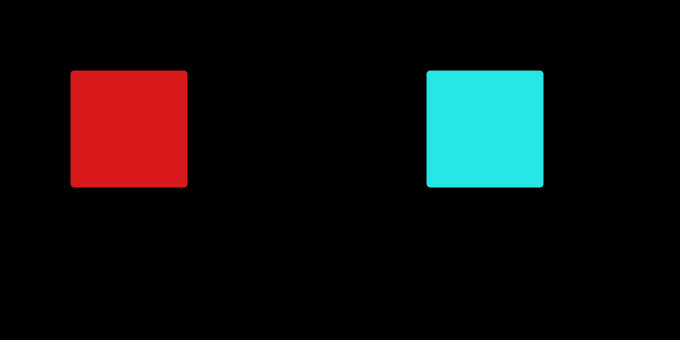
One adapting colour, two answers. The left patch is what was stared at. The middle is the afterimage the cone-gain arithmetic predicts at 15 per cent adaptation; the right is the inverted code values. They are 22.1 ΔE00 apart. The gains that produced the middle patch are 0.95, 1.06, 1.69 on the long, medium and short cone classes — the reciprocal of what each class had been receiving, taken 15 per cent of the way.

An afterimage is an adaptation

The demonstration everybody gives is an inverted image, which is a statement about a file format. Running the receptoral arithmetic instead puts the afterimage of a saturated red sixty degrees of hue away from the inverse — and outside what any display can show.

brain · Appearance
How far a judgement is from the settled one, second by second. The light changed from one white to another at t = 0 and nothing else moved. The model has one degree of adaptation and no clock, so the distance plotted is what a clock adds: 3.6 CAM16-UCS units half a second in, still 1.3 after a minute, and 0.11 after five. Every appearance number on this site is the value at the right-hand end.

The model has no clock

An appearance model takes a stimulus and a situation and returns what it looks like. It does not take a time, and adaptation is not instantaneous — half a second after the light changes a judgement is three and a half CAM16-UCS units from the settled one, and a minute later it is still 1.3.
limits · Limits
An afterimage, as the local pool coming back to equilibrium. The local pool has adapted to the patch and the global pool has not, so the gain change is exactly the local share of a full von Kries change — which is why afterimage's free strength parameter is not free here. The dwell is 20 seconds. The swatches are the predicted appearance of the test surface at four moments. They are predictions of hue and direction; there is no response compression in this model, so the chroma is a ceiling rather than an estimate.

A gain has a time constant

An afterimage and the clock on chromatic adaptation were built in different files from what the last phase said was one mechanism. Joining them removes a free parameter, reproduces both, and predicts a third thing — that two people in one room, at one moment, looking at one patch, do not agree about its colour.
brain · Appearance
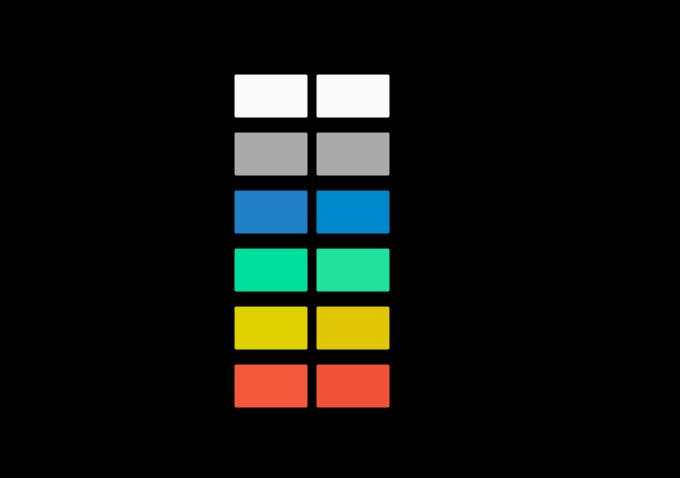
What the same eye reports about one field, in the middle and at the edge. Each row is a uniform field, drawn at the most saturated version of itself this page can show — the percentage is how much of the full stimulus survived, the rest being the adapting light added to bring it inside the gamut. The left patch is what the centre of gaze reports and the right one what 10 degrees out reports, each adapted to the same light as that position sees it. The adapting white comes out identical to 5e-13, because an adapted eye cancels its own filter exactly. Nothing else does, and the largest difference is in the blue. tungsten light is not drawn: it cannot be shown at any useful saturation, and at full strength it differs by ΔE00 1.87.

One person is two observers

The macular pigment is a yellow screen over the fovea and nowhere else, so a cone at the centre of gaze and a cone ten degrees away have different colour-matching functions in the same eye. A match made in the middle comes apart at the edge by six units — and fitting one filter to the gap between the CIE's two standard observers gives a density of 0.40 against a measured 0.35.

eye · Cones
A surface in a room, from the moment the light goes on. How far a blue surface is from the colour it will settle at, second by second, for an observer who walked in from the snow as the lamp was switched on. It starts ΔE00 27 away, is still 6.1 away after a minute — the point at which the eye is conventionally said to have adapted — and does not fall under a unit until 295 seconds.

The room settles after the eye does

Four clocks run in a room and only three of them are in the observer. The slowest is the lamp, which takes four hundred seconds to reach nine tenths of its colour change — so a minute after the light goes on, when the eye is conventionally said to have settled, most of what is left is the lamp, and three quarters of that could not be adapted away by an observer of any speed.

light · Light
The appearance model's three rooms, read as three moments. CIECAM16's degree of adaptation is a function of the surround and the adapting luminance and of nothing else — the model has no time in it. Solving for the moment at which an observer who will adapt completely has got that far turns each of the three tabulated surrounds into a reading on a clock. At 100 candelas per square metre they are 106, 49, 21 seconds. They are presented as three rooms. They are also one observer, in one room, at three times in the first two minutes.

A viewing condition is a moment

CIECAM16's degree of adaptation is a function of the surround and the adapting luminance and of nothing else, because the model has no time in it. Solving for when an observer who will adapt completely has got that far turns the standard's three surrounds into three clock readings — 107, 50 and 21 seconds — and the two readings are distinguishable by waiting.

brain · Appearance
A corner moves the spectrum and the viewing condition at once. A coloured patch in a corner of coloured walls, against how enclosed the corner is. The top curve is what a colorimeter set up at the door reports: light that has bounced carries the surrounding reflectance again, so the patch is lit by something the room is not. The middle curve is what is left once the patch is read against the corner's own white — most of it goes, because a corner is a change of illuminant and that is what chromatic adaptation is for. The bottom curve is the other thing a corner is: a brighter place, 1.76 times the light, which moves the appearance through the Hunt effect with the white point held still and cannot be adapted away at all.

A corner moves both terms

The interreflection essays compute what a corner does to a spectrum, which is one of the two things a corner does. It is also a brighter place with a differently coloured background — a viewing condition, not a stimulus — and adaptation removes most of the first and none of the second. At an enclosure of six tenths that is 63 per cent of seven units gone and a further unit arriving from the extra light alone.

scene · Scene
Every change of light this site models, and how much of it a gain removes. Each row is a change of illumination. The pale bar is how far it moves an ordinary surface for an observer who does not adapt; the solid bar at its left end is what is left after the observer has applied the one gain adaptation gives them, which is the ratio of the two whites in the CAT16 basis and is not fitted to anything. Sorted by the fraction left rather than by the size of the change, because the two orderings are different: the largest change here is removed almost entirely and the worst row is a change less than a third its size.

What no adaptation can remove

A change of light is exactly a 3×3 matrix on tristimulus values, and adaptation is a diagonal one. Putting every change of illumination this site models through that distinction sorts them by how much of themselves they leave behind, and the smallest residual in the census belongs to a filter inside the eye.

limits · Limits
Every published adaptation transform, and one computed from daylight, on every change. What each basis leaves an adapted observer with, row by row. Darker is worse. The last column is not a published transform: it is the basis in which a change from D65 to D50 is exactly diagonal, computed in closed form from the two spectra with nothing fitted. It is far the best on the daylight rows and it is beaten on the discharge lamps, which is the trade the published transforms are sitting in — they were fitted to data containing both kinds of light and are therefore optimal for neither. Over the census as a whole the winner is Bradford at ΔE00 1.14.

A gain needs a basis

Adaptation scales three signals, and which three is a choice. The basis in which a change from D65 to D50 is exactly diagonal can be computed in closed form from the two spectra, it beats every published transform on daylight by a factor of five, and it loses to all of them on a fluorescent tube.

brain · Appearance
The share of itself each change leaves behind, and the smallest is inside the eye. The residual as a fraction of the change rather than as a colour difference, which sorts the census differently. At the top is the macular pigment — the filter in front of the central few degrees of one's own retina — leaving 2.4 per cent of itself. It is a fixed transmittance multiplying the light and the white together, which is as close to a pure gain as anything here gets, and it is why nobody notices they have one.

The filters inside the eye

The macular pigment leaves 2.4 per cent of itself after adaptation — the smallest share of anything in this site's census of light changes, and less than half the next smallest. Fifty years of lens yellowing leaves 7.9 per cent, and the difference between the two says what a gain is actually good at.

eye · Cones
The basis a camera balances in is a different basis for every light. A camera's white balance is a per-channel gain on raw values, which is a von Kries adaptation in whatever basis the filter dyes give it. That basis is not a property of the dyes alone: it is the dyes and the light in the room, and it moves when the light does. Each bar is how far the basis has turned, in degrees, from where it sits under D65. A sensor satisfying the Luther condition would have a bar of exactly zero on every row, because for such a sensor the light cancels — which is the one property nobody buys a sensor for.

A camera balances in another basis

White balance is a per-channel gain on raw values, which makes it a von Kries adaptation in whatever axes the filter dyes happen to give. Those axes are not a property of the dyes alone — they move with the light, by up to seventeen degrees across the adaptation census — and the sensor for which they would not move is the one that adapts worst of all.

imaging · Capture
Media-relative colorimetry is a von Kries adaptation in the worst basis there is. Changing the paper is a change of the light reaching the reader, and the rule colour management uses for it — divide the tristimulus values by the substrate's — is a gain applied in XYZ. That is the one transform the table here describes as the oldest mistake still shipping. On the three stocks a press actually uses the penalty is real and small, because a sheet of paper-mill white is the smoothest change of light in the census. On blue it is 10.2 times the residual the same rule would leave in a cone basis.

Dividing by the paper

Media-relative colorimetry divides tristimulus values by the substrate's, which is a von Kries adaptation applied in XYZ — the one basis the table here describes as the oldest mistake still shipping. On a paper-mill white it costs a few hundredths of a unit. On a tinted sheet it costs ten times what the same rule costs in a cone basis.

applied · Delivery
Four devices, and what each of them can do about a change of light. The mean over the census of what each device is left with. A press has no mechanism, so its number is the whole change — a printed sheet does not adapt to the room it is read in. A display can move its white point, which is a gain in its own primaries. A camera applies a gain in whatever basis its filter dyes happen to give it. And the sensor that satisfies the Luther condition exactly is worse than the silicon one — satisfying the condition means its channels are the matching functions, and a per-channel gain on the matching functions is the transform this site calls the oldest mistake still shipping.

Only one of these devices adapts

An eye, a camera, a display and a press all meet the same changes of light, and each has at most one thing it can do about them. The press has nothing at all, so its column is the whole change; and this collection's sensor built to satisfy the Luther condition exactly is the one that adapts worst.

limits · Limits
Where each published matrix puts the confusion points, whether or not it meant to. Every matrix from tristimulus values to cone responses commits itself to three confusion points, because the point is the direction the other two rows annihilate. The first row is the construction from the measured points and returns them exactly. The rest were chosen for other reasons and land elsewhere — Hunt–Pointer–Estévez, which this collection uses everywhere, misses the deuteranope's point by 1.28 in chromaticity. The worst here is 4.09.

The cones an appearance model uses

CIECAM16 adapts in three axes whose rows are labelled L, M and S, and they were fitted to corresponding-colour experiments rather than measured on receptors. Run the dichromat construction backwards on them and they commit to a deuteranope confusion point 1.45 away in chromaticity from the measured one — which is a test the axes were never asked to pass.

brain · Appearance
Four different bases, one adaptation model, one number. The middle row of the basis built from the confusion points multiplied by 0.21, 1, 3.7 and 11 in turn, with the resulting adaptation residual drawn as a bar in each case. The four bars are the same height to 9e-16 of a ΔE00, because the row's scale cancels exactly between the gain and the inverse. Three of the nine numbers a colour match leaves free are invisible to an adaptation model, which is why the six the dichromat data supply determine it outright with nothing left to fit.

The three numbers a gain cannot see

Colour matching leaves nine numbers free. Three dichromat confusion points fix six of them and three choices of unit fix the rest — and it turns out that a von Kries gain is exactly blind to those last three. So the dichromat data do not merely constrain an adaptation basis. They determine it, with nothing left over to fit.

eye · Cones
How cone-like a basis is, against how well it adapts. Each basis placed by how far its own implied deuteranope confusion point falls from the measured one (horizontal) and by how much an adapted observer is left with in it (vertical). The construction from the confusion points sits at zero on the horizontal by definition and near the top on the vertical. Nothing near the left of the picture is near the bottom: the closer a basis is to the receptors, the more a von Kries gain leaves behind. The unconstrained winner sits at 1.63 on the horizontal, further from the measurement than any published transform except CAT02 and Bradford.

The best axes are not receptors

If the axes that make a von Kries gain work were nearly the cone fundamentals, the published adaptation transforms would be cone-like and their departures would be slack in a fit. They are not. Minimise the residual over all nine free numbers and the winner sits further from the measured dichromat confusion points than any of them.

eye · Cones
Every basis against both objectives at once. A scatter with the mean adaptation residual across the illumination census on the horizontal axis and the mean axis ratio of MacAdam's ellipses in a lightness–chroma space on the vertical. Lower is better on both. The two winners sit at the two ends of an empty diagonal: the basis that adapts best leaves 7.70 on the vertical and the basis that discriminates best leaves 1.79 on the horizontal, each worse on the other objective than every published transform. The basis built from the dichromat confusion points is at (1.65, 2.60) — best at neither and within a factor of two of both floors, which no other entry in the picture manages.

No basis is good at both

The same nine numbers decide how well a von Kries gain reproduces a change of light and how nearly a lightness–chroma space makes the discrimination ellipses circles. Minimise either one and the other collapses. The basis built from the receptors is best at neither and is the only entry in the table respectable at both.

brain · Appearance
How far from circles every basis leaves the ellipses. Eight bases ranked on the mean ratio of the long to the short axis of MacAdam's twenty-five discrimination ellipses, measured in a lightness–chroma space built on that basis. The range runs from 1.61 for best for discrimination to 7.70 for best for adaptation. The ordering is not the ordering on the other objective and is nearly its reverse.

One matrix doing two jobs

CIECAM16 adapts in CAT16 and then applies its response compression in the same axes, so a single matrix decides both how well the model handles a change of light and how uniform the space it produces is. The two jobs have different best answers, and the matrix was chosen against only one of them.

brain · Appearance
Every change of light in the census, under three bases. Fourteen changes of illumination, each drawn three times: the residual left by a gain in the basis built from the dichromat confusion points, in CAT16, and in the basis that minimises the average. The ordering between the three is the same on nearly every row, and — the part an average hides — the worst row is the same row for every basis nobody fitted, which is two bounces off the same wall. The difficulty belongs to the change rather than to the choice of axes — except for the fitted winner, whose worst row is D65 to a triphosphor tube instead. What a fit buys is not a uniform improvement; it is the abandonment of the one change everybody else is beaten by.

Which changes of light pay for it

A fitted adaptation basis beats the receptors by 0.68 units on average, and an average is a poor description of what it does. On six of fourteen changes of light it is worse, and the whole of its advantage comes from four — a tungsten lamp and three coloured walls.

light · Light
Every change of light in the census, under three bases. Fourteen changes of illumination, each drawn three times: the residual left by a gain in the basis built from the dichromat confusion points, in CAT16, and in the basis that minimises the average. The ordering between the three is the same on nearly every row, and — the part an average hides — the worst row is the same row for every basis nobody fitted, which is two bounces off the same wall. The difficulty belongs to the change rather than to the choice of axes — except for the fitted winner, whose worst row is D65 to a triphosphor tube instead. What a fit buys is not a uniform improvement; it is the abandonment of the one change everybody else is beaten by.

Everyone is beaten by the same wall

Eight candidate adaptation bases, fourteen changes of light, and seven of the eight have their worst row in the same place — not a lamp, but a green wall reflecting twice. The one that does not is the one that was fitted, and what its fit bought was permission to give up on that row.

light · Light
Three published primary sets, and a fourth chosen for how it adapts. The spectral locus with four triangles inside it. sRGB covers 33.5% of the diagram and leaves an adapted observer 2.36 ΔE00; Display P3 covers 45.4% at 1.22; Rec. 2020 covers 63.3% at 1.09. The fourth triangle is the best adaptation basis available to a display asked to cover 63.5% of the diagram, at 1.02 — and it is a different triangle from Rec. 2020's rather than a smaller one. The largest triangle that fits at all covers 73.9%, which is where the axis of this argument ends.

Primaries chosen for their inverse

Moving a display's white point is a gain on its R, G and B, so a display adapts in the inverse of its own primary matrix — a basis chosen by committees for gamut coverage and phosphor availability. Pose the design problem properly and the answer costs one per cent of the gamut argument and reaches within two per cent of the best basis there is.

applied · Delivery
A display's primaries, scored as the adaptation basis they are. Four primary sets ranked by the mean ΔE00 an adapted observer is left with when the white point moves — which for a display is a gain on R, G and B, and so a von Kries adaptation in the inverse of its own primary matrix. sRGB leaves 2.36, as much as scaling XYZ directly and therefore as much as having no cone basis at all. Rec. 2020 leaves 1.09, better than every published adaptation transform fitted to corresponding-colour data. Nobody chose that: it is what wanting a wider gamut does to a primary's spectral selectivity.

The gamut race chose the basis

Twenty years of arguing about how much of the diagram a display should cover has produced primaries whose inverse is a better adaptation basis than any transform ever fitted to corresponding-colour data. On the invariant count of what those displays can actually show, the same twenty years produced nothing at all.

matching · Gamut
The dyes a camera has, and the dyes an adaptation basis would want. Three sensor sensitivities drawn twice: faintly, the silicon-and-filter-array set this collection models, and boldly, three Gaussian dyes chosen to make the inverse of their own response matrix a good basis for a white-balance gain. The designed dyes sit at 610, 542, 449 nm with widths of 35, 26, 30 nm — narrower and further apart than the real ones, which is what sharpening looks like when a search rather than a committee does it. They leave 0.97 ΔE00 against the real sensor's 1.62, and they are held within 0.28 of the Luther condition so that the result is still a camera.

A sensor designed for its inverse

A camera's white balance is a gain in a basis made from its own dyes and the light in the room. Choose the dyes for that basis instead of for cost and quantum efficiency, hold the sensor within a stated distance of the Luther condition, and the design reaches the best adaptation figure any basis achieves — and then the room moves it.

imaging · Capture
Four cameras that all satisfy the Luther condition exactly. Four sensors whose sensitivities are linear combinations of the colour-matching functions — the theoretical ideal, satisfying the condition to machine precision, each with an adaptation basis that does not move when the light does. They differ only in which linear combination, which the condition does not constrain, and they leave 2.46, 0.97, 1.65, 2.37 ΔE00 after a white balance. The best of them reaches 0.974, which is the best any basis at all achieves. Being a perfect colorimeter costs nothing in adaptation; what costs is the mixing matrix, and the control measured here carries one nobody chose.

The condition chooses no axes

It has long been said here that a sensor satisfying the Luther condition exactly adapts worse than a silicon one, and offered a reason — that its channels are the matching functions, and a gain on those is the oldest mistake in the subject. The measurement was of one sensor. The condition leaves the axes entirely free.

imaging · Capture
Nine eigenvalues, six of which exist. Nine points on a logarithmic vertical axis: the eigenvalues of the Hessian of the adaptation residual at its own optimum, largest to smallest. The first six run from 6.8×10² down to 7.6×10⁻¹, a condition number of 890. Then the axis drops: the seventh is 1.9×10⁻⁴, and the last three are separated from the sixth by a factor of 4.0×10³. Those three are not small curvatures. They are the finite-difference truncation error on directions along which the objective is exactly constant, and a shaded band marks them as the numbers the objective does not have.

The rank is the invariance

A von Kries gain cannot see the scale of a row of its basis. That is an identity, proved in a line, and it can be measured instead — as the rank of a second-derivative matrix. Both objectives this collection minimises over the observer's nine free numbers have a Hessian of rank exactly six, and the three directions they cannot see are the three scalings, to a hundredth of a degree.

eye · Cones
The bowl the eigenvalues describe and the bowl a sample found. Six points on a logarithmic vertical axis — the distance from the optimum of the adaptation residual to a 5 per cent rise along each of the six directions the objective can see — with a shaded band behind them showing the whole range 24 random directions reported. The eigen-radii run from 1.2e-2 to 3.6e-1, a factor of 29.8. The band runs from 2.2e-2 to 1.8e-1, a factor of 8.0, and sits entirely inside the ends of the true range: a random direction in nine dimensions carries a share of every eigenvector and so reports the middle of the bowl, never an end of it.

How long is the bowl

The optimum of an adaptation objective is twenty-nine times longer one way than another, and the two ends have names — the stiffest direction is almost entirely the short-wavelength row of the basis, the flattest almost entirely the long-wavelength one. Twenty-four random directions reported a factor of eight, and no number of them would have done better.

matching · Gamut
The worst case is wherever the box stops. Four horizontal tracks, one per parameter of a painted wall. Each track spans the range an ordinary paint is allowed to occupy, with a second, wider range drawn behind it, and two markers show where the search for the worst change of light came to rest under each. Under the narrower box the answer sits on the wall in centre and width; under the wider one, in centre, width, base. The residual rises monotonically towards a narrower notch at a shorter wavelength on a darker wall, so there is no interior maximum to find. The worst change of light is 21.3 ΔE00 under one box and 28.4 under the other, and the census's own worst row is 3.37.

The worst case is where the box stops

The worst change of light this collection quotes is two bounces off a green wall, and it is the worst of fourteen changes somebody wrote down. Searching the family those fourteen were drawn from reaches six times further — and does not stop, because the residual rises monotonically towards a narrower notch on a darker wall. There is no worst case in this family, and the number anybody quotes for one is a number about their own constraint.

scene · Scene
Best on the average, undefined at the edge. Two rows of bars sharing one set of labels. On the left, each adaptation basis's mean residual over the fourteen changes of light the census lists — Bradford is the shortest bar at 1.14 ΔE00 and is what colour management uses. On the right, the same bases against the worst change the same family of painted rooms can produce. Three of the five have no bar there at all, marked instead with the gain that replaced it: under a deep narrow notch their reading of the white passes through zero, so the diagonal is a division by nothing and the model stops being defined rather than merely doing badly. Bradford's middle gain reaches -1.0e+19. CAT16, which exists because CAT02 was withdrawn for going negative in practice, is one of the two that survives.

Best on the average, undefined at the edge

Bradford has the lowest mean residual of any adaptation transform over the census of illumination changes, which is why colour management uses it. Inside the family that census was drawn from, its middle row's reading of the white passes through zero — so the gain is a division by nothing, and the model stops being defined rather than merely doing badly. CAT16, which exists because its predecessor did this, does not.

applied · Delivery
What the confusion points charge, across a population. A histogram of 200 members of a population of eyes, each scored by what the adaptation basis their own confusion points determine leaves after the gain. It runs from 1.22 to 2.24 ΔE00 with a median of 1.78. Vertical marks show the unconstrained floor at 0.97, the published transforms, and the single observer this site quotes at 1.65. The distribution straddles Hunt–Pointer–Estévez and reaches below CAT16: 18 per cent of members are better served by their own receptors than by a matrix built to make a gain behave, and 2 per cent than by the current recommendation.

The price is also the person

The receptor construction costs seventy per cent above the unconstrained floor, which is a number usually quoted as a property of the construction. Propagated across a population of eyes it runs from a quarter above the floor to a hundred and thirty per cent above it, and the population's own spread is wider than the entire gap between the published transforms the seventy per cent was being compared against.

limits · Limits
Every adaptation number here assumes a complete adaptation. Three curves and their mean: the colour difference an adapted observer is left with after a change of light, against the degree of adaptation from zero — no adaptation at all — to one. Every adaptation figure in this collection is computed at one, the right-hand end. The appearance model's own formula puts the degree at 0.941 for an average surround at a hundred candelas, marked, where the residual is 2.21 ΔE00 rather than 1.27 — larger by a factor of 1.74. The left-hand end is exactly the unadapted change, which is not an approximation but an identity, and is what says the curve interpolates between the two things it claims to.

A discount nobody measured

Every adaptation number in this collection assumes an observer who adapts completely. The appearance model's own formula says they do not — it puts the degree at 0.94 in an ordinary room — and the difference is not a rounding. It is a factor of 1.7 on the residual every one of those figures reports.

brain · Appearance
The family does have a worst case, at a band no pigment can cut. The worst change of light a painted wall can produce, at each band width, with the wall's centre wavelength, depth and base optimised at every point. The horizontal axis is logarithmic in the width. The curve rises as the band narrows, turns over at about 6.02 nanometres, and falls again — a band that narrow returns too little light to move the white much. The previous round's search reported no worst case because its box stopped at ten nanometres, marked, which is on the wrong side of the turn. The peak is 28.54 ΔE00 against 28.38 at that floor, which is 0.6 per cent higher: wrong in principle, right in practice to a fraction of a per cent.

A notch a pigment cannot cut

The worst change of light a painted room can produce has no maximum inside the box the search was given, which the previous round reported as a family with no worst case. Bounded by what a molecule can actually do, it has one — at a band six nanometres wide, narrower than any pigment and narrower than the box.

light · Light
The winner survives the census's own construction; the middle of it does not. One row per perturbation of a constant the adaptation census is built from — the imaginary wall's centre wavelength, its width, its depth, its base, the macular filter's density and the two lens ages — each moved by an amount plausible for that quantity in its own units, up and down, and then all of them together. Each row shows where the five published transforms rank under it. Bradford holds the first column in all 14 rows. The second and third columns, which the table as built separates by six parts in a thousand, change places in 2 of them — so that ordering was never a fact about the transforms.

The census is a construction too

Five of the fourteen changes of light this collection scores adaptation transforms against are not measurements of anything — they are a wall somebody invented, at a wavelength somebody chose. Moving those constants by amounts plausible in their own units moves the mean residual by two fifths and never changes which transform wins.

light · Light
A room applies its wall a different number of times at each wavelength. The mean number of bounces the surviving light has made, wavelength by wavelength, in a closed room whose walls are the green paint the adaptation census uses. It runs from 0.33 in the band the wall absorbs to 5.67 in the band it reflects — a factor of 17.00 — because the light that survives many bounces is the light the wall was reflecting all along. The census has one bounce and two bounces as separate rows and a search treats the count as a free integer; a room has neither, and what it has is bounded by the walls reflecting less than everything.

A room bounds its own bounces

The adaptation census has one bounce and two bounces as separate rows, and a search over the family treats the count as a free integer it always takes to the largest value offered. A room offers no integer at all — it applies a geometric mixture of every number of bounces, and that mixture is bounded by the walls reflecting less than everything.

scene · Scene
Exactly flat everywhere, and eigenvectors at one point only. Two columns over the same nine places. On the left, how far from zero the objective's second derivative is along a row-scaling direction, on a logarithmic axis — it is between 10⁻⁹ and 10⁻⁶ of the largest eigenvalue at every one of them, which is a numerical zero. Scaling a row of the basis is a straight line along which the cost does not change, and that is true at every point, not only at the optimum. On the right, the angle between those three directions and the Hessian's own three smallest eigenvectors: 0.025 degrees at the optimum and up to 88 away from it. An invariance is a property of the function; being an eigenvector is a property of the function at a minimum, and the two coincide only where everybody computes.

Only the flat directions keep their names

Three of the nine numbers a colour match leaves free do nothing, and they do nothing everywhere — exactly, at every basis in this collection's table. They are the objective's own principal directions at one point only, and everywhere else the directions carrying the curvature have turned by tens of degrees.

matching · Gamut
What one change of light costs, surface by surface — daylight to tungsten. A rising curve of 125 points, one per surface in the test set, sorted from the surface this change of light costs least to the one it costs most, with the published mean drawn across it as a horizontal line. The published residual for daylight to tungsten is 1.635 ΔE₀₀. The curve runs from 4.4e-14 — 5 of the surfaces are flat greys, on which an adapted observer's gain is exactly right and the residual is exactly zero — to 3.058, which is 1.87 times the mean. The mean line crosses the curve about two thirds of the way along, so most surfaces cost less than the published number and a minority cost a great deal more. This is what a single published residual is a summary of.

A mean has a set under it

Every adaptation number this collection publishes is an average over a hundred and twenty-five surfaces that were written down once, in one file, with no argument for how many there should be or how saturated. The average runs from exactly zero to twice itself across them, and the set has never been varied.

scene · Scene
What a fourth reflectance dimension costs the theorem that a change of light is a matrix. Four rising curves on axes of the fourth dimension's amplitude, left to right, against what is left of daylight to tungsten after the exact 3×3 change-of-light matrix has been applied, in ΔE₀₀. All four begin at exactly zero: on the three-dimensional family the matrix is solved rather than fitted and there is no remainder at all, which is the theorem this collection's adaptation argument is built on. Adding a fourth reflectance dimension breaks it, and how badly depends far more on the fourth function's shape than on its size — at five per cent amplitude the four shapes cost 0.329, 0.572, 0.063, 0.124 ΔE₀₀ respectively, a factor of 9.1 between the dearest and the cheapest. For scale, the smallest von Kries residual anywhere in the census is 0.26 ΔE₀₀, so the cheapest of the four is a quarter of it and the dearest is twice it.

A theorem about a family

A change of light acts on the test surfaces used here as an exact 3×3 matrix with no residual whatsoever, and the whole adaptation argument is built on that being exact. It is exact because the surfaces span exactly three dimensions, and they span exactly three dimensions because three basis functions were written down.

scene · Scene
No one surface carries the answer, and the set is smaller than it looks. A falling bar chart of the 125 surfaces in the test set, ordered by how much each contributes to the published mean for daylight to tungsten. The tallest bar is 1.50 per cent of the total, so the mean is not a few awkward objects with a crowd behind them and a leave-one-out would move it by well under a per cent. The tail is the other half of the story: 5 surfaces contribute essentially nothing, because a flat grey is a surface an adaptation gain handles exactly. Counting the set by how evenly it contributes rather than by how many members it has gives 108.5 effective surfaces out of 125, which is what "a mean over a hundred and twenty-five surfaces" is really worth.

The surfaces that answer nothing

Five of the hundred and twenty-five test surfaces contribute exactly zero to every number the adaptation census reports — not approximately, exactly — and the reason is the one fact about von Kries adaptation that makes it worth having at all. Counting the set by how much it contributes gives about a hundred members rather than a hundred and twenty-five.

eye · Cones
The adaptation census in six units, calibrated onto one scale. Each line is one of the fourteen changes of light in the adaptation census, drawn across the six units the results could have been published in. Every unit is multiplied by the single factor that best carries it onto ΔE2000 over a reference sample of surface pairs, so the vertical axis means the same thing in every column and a sloping line is a disagreement rather than a change of scale. The levels move by up to a factor of two. More to the point, the lines cross: ΔEok puts 10 of the 91 pairs of rows in the other order, and CAM16-UCS, the only appearance unit here, puts the fewest — 2.

The census in six units

Recomputing every change of light in the adaptation census under six colour-difference formulae, with the scale factor divided out, leaves a table whose levels move by up to a factor of three point seven. The rows that move most are the mild ones, which is the opposite of what a reader would guess and is a property of where each formula was fitted.

light · Light
What an observer is left with, by how much it is allowed to know about the room. Six ways of discounting a change of light, averaged over the fourteen changes in the adaptation census and 125 test surfaces each. The bar is what each leaves behind, on a logarithmic axis because the models span two orders of magnitude. The second line under each name is the count that matters: how many numbers about this room the model has to be given. Doing nothing leaves 15.7 ΔE₀₀. A single gain read off the two whites' luminances leaves 15.3. A matrix fitted across half the census and then applied everywhere, knowing nothing about the room at all, leaves 12.5. The published von Kries gain, which is told the white and nothing else, leaves 1.312 — and bolting a fixed correction onto it, at no cost in scene information, leaves 1.368, which is very slightly worse. The exact matrix leaves nothing and is not on the chart: its nine numbers are the change of light, which is the quantity being discounted.

Three numbers the scene supplies

An adaptation model's parameters are not all the same kind of thing. Some are numbers an observer must estimate from the room it is standing in; others could have been settled once by evolution. Counting them separately turns the diagonal gain from a crude approximation into the only model of the set that gets a large answer from information the observer can actually have.

scene · Scene
How much of the residual a partial correction removes. Between the diagonal gain and the exact matrix there is a line: apply the correction that would make a row exact, but only a fraction of it. The horizontal axis is that fraction and the vertical is the share of the row's residual it removes, for all fourteen census rows. The straight diagonal is where a correction worth exactly its fraction would fall, and in the published unit every curve lies on it to within 2.2 percentage points. The lower band of curves is the same interpolation measured in CAM16-UCS, which departs by up to 17 points — because its distance is a power of the Euclidean one and a power is not homogeneous along a ray, where every ordinary norm is. The straight line is therefore a property of the ruler rather than of the correction, and the exception is what says so.

A partial correction is worth its fraction

Between a diagonal gain and the exact matrix there is a line, and a bounded observer's natural hope is that the first part of it is worth a disproportionate share. It is not. On all fourteen changes of light, at every setting, the share of the residual removed matches the share of the correction applied to within 2.2 percentage points — which closes the last way the gap could have been cheap.

scene · Scene
A correction an observer could have been born with, fitted on half the census and tested on the other. The same six models, each scored twice: on the seven census rows the fixed matrices were fitted to, and on the seven they were not. The split alternates by position so both halves contain daylight changes and discharge lamps. The upper bar is in sample and the lower is out, on a logarithmic axis. For the four models with nothing fitted the two bars differ only because the halves are different questions. For the two fitted ones the gap is the finding, and it is largest where it matters least: bolting a fixed correction onto the von Kries gain takes it from 1.2724 to 1.2592 on the rows it was fitted to, and from 1.3511 to 1.3679 — worse — on the rows it was not. There is no correction to the diagonal that an observer could arrive with.

A model is a claim about what can be known

The exact answer to chromatic adaptation is nine numbers, and the nine numbers are the change of light itself. A model whose parameters are quantities the observer cannot obtain is not a worse model of the same thing — it is a model of something else, and counting parameters without asking where they come from hides the difference.

scene · Scene
The three cone absorptances at two settings of the cone optical density. Solid and dashed are the same construction at the two ends of two standard deviations of the reported spread. The curves are built from one pigment template through its ocular media, which is the same model its population of two hundred eyes is drawn from. The largest difference between the two sets is 18.8 per cent of the peak, and where it sits along the wavelength axis is what decides which stimuli the two observers disagree about — a departure concentrated in the blue is invisible on a sample with no blue in it.

A gain is not an observer

Multiply one eye's three cone sensitivities by 1.6, 0.7 and 2.4 and it is not a different eye. The white-point division is that multiplication's inverse, so the two agree exactly — and most of what a cone optical density change does is that multiplication, which is why the largest number in the table of individual variation is the one that matters least.

eye · Cones
What choosing a space to divide the white out in is worth. Three pairs of routes to the same colour, over forty-two surfaces: dividing the white out in tristimulus values, in a published cone space, and in the observer's own cones. The first two agree to 0.59 ΔE₀₀ at the median. Either of them differs from the observer's own cones by more than fifteen. That is why the two exact conditions in this round are exact only in the eye's own coordinates: the identity belongs to the receptors, and every published arithmetic works in a basis somebody else chose.

The identity is in the eye's own coordinates

Two conditions in this round are exact — a gain on each cone is not a different observer, and three curves for one space are one observer. Imposed in a published cone space rather than the eye's own they leave 13.0 and 8.11 ΔE₀₀ standing. The identities belong to the physiology and every arithmetic in use works somewhere else.

eye · Cones
Each departure over forty-two surfaces rather than one. The same six departures measured over a family of forty-two analytic reflectances — an absorption band of stated centre, width and depth — with the smallest, the median, the ninety-fifth percentile and the largest marked. Every one of them spans more than a factor of three, and the ranking between them is not stable across the family: what decides a departure's size is which sample it is asked about, because a departure is a pairing and the sample is one of the two factors. Quoting any single number for what an observer's age is worth is quoting a choice of example.

The census under another observer

This collection's largest computed result is an adaptation census — fourteen changes of light judged over a hundred and twenty-five constructed surfaces. Every number in it was computed through one observer, and the observer's own departures are between one and two and a half units on the same surfaces, which is the size of the effects the census reports.

brain · Appearance
The conditions under which an observer's departure is exactly zero. A departure of the observer is the pairing of something belonging to the observer with something belonging to the stimulus, so emptying either factor empties the product. The axis is logarithmic in what is left when the condition is imposed. Six rows empty the stimulus's factor — a perfectly neutral sample is the same colour for every observer, at any age and any field size — and two empty the observer's, since a gain on each cone and a change of basis are both absorbed exactly. All eight are identities rather than small numbers. The last two are the same two conditions imposed in a published cone space rather than in the observer's own, and they are worth eight and thirteen units: the identity is about the eye, and the arithmetic everybody uses is in somebody else's coordinates.

The conditions are the result

The round measured about twenty departures and established ten conditions. The departures are numbers that depend on a sample, a light and a construction; the conditions are exact, they hold under every substitution tried, and they are what a reader can act on. A size is a measurement and a condition is a mechanism.

limits · Limits

Named alongside it

The objects these essays reach for when they reach for this one.

Chromatic adaptationBasisCAT16AdaptationAssertionCone fundamentalsReflectanceIlluminantWhite pointColour constancyTest setCIECAM16

All concepts